
Marketing Mix Modeling Consulting: A 5-Phase Process Based on Real-World Experience

On 23 July, Dr. Simon Hannemann, Manager Marketing Science at Hopmann, showed at our Raw & Roasted how a Marketing Mix Modeling consultancy engagement actually runs in practice, from the first data selection through to the budget decision. It was our last Raw & Roasted before the summer event break, and a particularly good one to end on: for the first time, the format ran hybrid, with some guests joining in person at our Munich-Neuhausen office and others via Zoom. The audience was unusually active, with a large part of the morning turning into a lively Q&A. The recording of the talk is now available.
Key insights from our Raw & Roasted with Dr. Simon Hannemann:
- A Marketing Mix Modeling consultancy engagement at Hopmann follows a fixed 5-phase process: data selection & collection, data preparation, modeling, validation & adaption, and results.
- Rule of thumb for the data foundation: at least two years of weekly data and ten observations per model parameter.
- Bayesian tools such as Meridian or PyMC Marketing return an uncertainty range for each channel’s effect, not just a single point estimate.
- A robust model needs two validation steps: statistical and business. Only both together make the results actionable.
- The audience was unusually engaged: a large part of the morning turned into a lively Q&A with both in-person and online guests.

The 5-phase process of an MMM consultancy engagement
“MMM should not be used to win arguments about the past, but to make better decisions about the future.” With this guiding principle, Hannemann summed up exactly what a Marketing Mix Modeling engagement is meant to answer: which channels actually drive revenue, and where should the next budget go? We’ve already covered how MMM works and why the method is gaining relevance right now in our blog series.
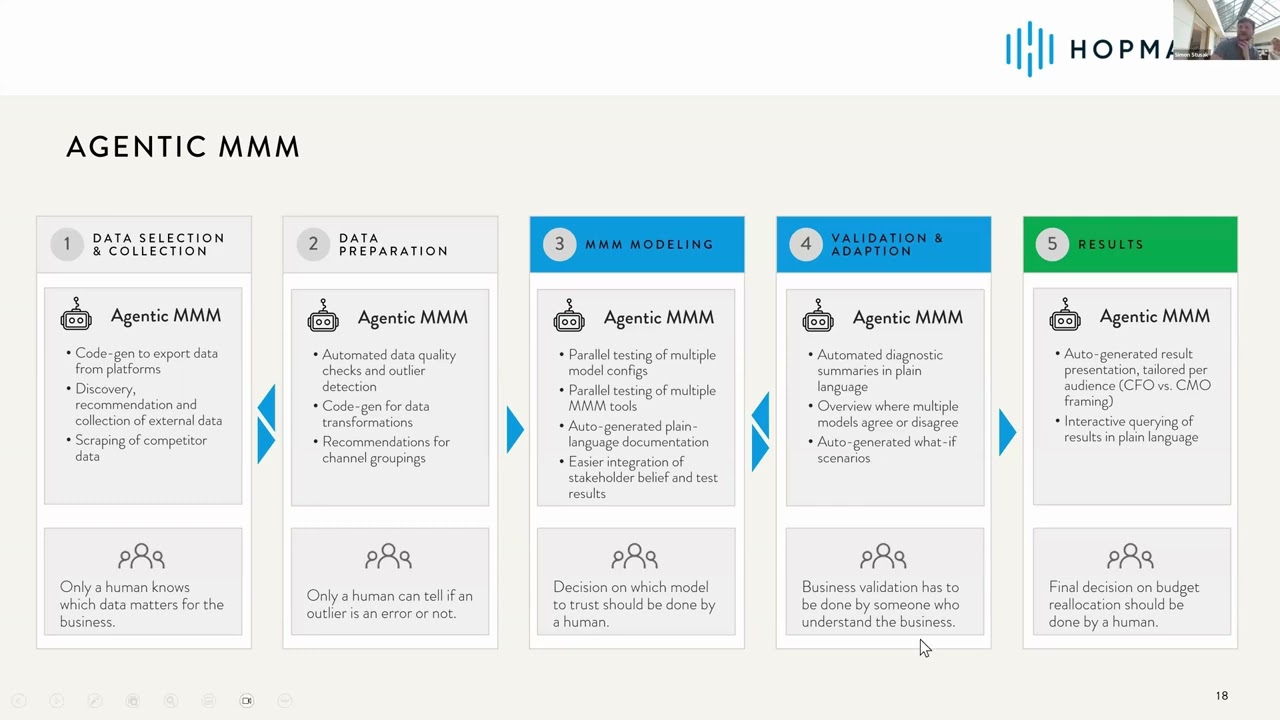
In Hopmann’s consultancy practice, MMM projects run often through five phases.

1. Data selection & collection
The first step is defining the target variable, usually revenue, sometimes conversions or installs. On KPIs, Hannemann recommends starting broad and then narrowing down deliberately, more KPIs are not automatically better. For data volume, a clear rule of thumb applies: at least two years of weekly data and ten observations per model parameter. At 104 weeks, that works out to around ten parameters, for example six media channels plus four context variables. If you want to check which data categories you actually need, our MMM data requirements checklist and the related blog post on data requirements give a detailed overview.
2. Data preparation
Next comes quality control: completeness, duplicates, outliers, and multicollinearity between channels. Particularly important, according to Hannemann: missing values, incorrect granularity, or too little variation in spend make it significantly harder for the model to detect a channel’s effect at all.
3. Modeling
Hopmann prefers Bayesian open-source tools. Meridian from Google is deeply integrated into the Google ecosystem and natively supports reach and frequency data as well as geo-based modeling. PyMC Marketing, a Python library from PyMC Labs, follows a similar approach and additionally offers ready-made building blocks for adstock and saturation curves, plus built-in budget optimisation. Both tools let you feed in existing knowledge, for example from lift studies, as a prior, and work throughout with Bayesian posterior distributions, meaning every result comes with an uncertainty range rather than a single number. Robyn from Meta takes a different approach: it combines ridge regression with constraints and relies on multi-objective optimisation via evolutionary algorithms (Nevergrad) for calibration, so it is not Bayesian. We’ve compared all three tools, Robyn, Meridian, and Orbit, in detail in Part 3 of our MMM blog series.
4. Validation & adaption
Every model goes through two checks. Statistical validation measures how well the model reflects actual sales figures, for example via R² or MAPE. Business validation checks whether the results are plausible from a domain perspective, for example whether the channel ranking matches what the media team has observed in practice. Both steps matter equally, says Hannemann: a statistically clean model can still lead to poor business decisions if relevant variables are missing. If the fit isn’t good enough, channels get regrouped, context variables adjusted, and the model run again.
5. Results
At the end, three concrete outputs emerge: each channel’s contribution to revenue, insights into carryover and saturation effects per channel, and a recommendation for reallocating budget.

This is exactly where the forward-looking framing from the opening comes back into play: these three outputs aren’t a look backwards, they’re the foundation for the next budget decision.
What you can take from our consultancy practice
For a model to detect signals at all, marketing activity needs to be designed for measurability from the start: spend should vary noticeably over time rather than simply following the calendar, and not all channels should be scaled up or down at the same time. If you want to test whether a channel works, do it repeatedly and in a controlled way rather than just once. And MMM should never be the only measurement method. Incrementality tests and attribution provide additional signals that help cross-check model results. One point from the lively Q&A stuck with the room: MMM doesn’t just help with the budget decision itself, it also helps separate the team’s emotional attachment to a channel from its actual effect, for instance when a channel “feels” like it’s working but the data shows something different. We’ve covered where Marketing Mix Modeling reaches its limits, and which myths persist, in Part 2 of our MMM blog series.
Where AI supports the process
Towards the end, Hannemann also gave a brief outlook on AI in the MMM process: in data collection, AI can help script data exports; in data preparation, it takes over quality checks; and during modeling, several configurations can be tested in parallel. What AI doesn’t replace: statistical and domain judgement. A model can report a high R² and still be misleading if an external confounder, such as a competitor campaign or a market shift, is missing. Recognising that remains a job for people with business understanding, not for AI. Which KPIs matter commercially, whether an outlier is an error or a genuine signal, and whether a budget actually gets reallocated, all of that continues to be decided by the consultancy team together with the client.
Marketing Mix Modeling remains what it should be in any good consultancy engagement: a process that works best when clean data, statistical craft, and business judgement come together. If you’d like to gauge where your own organisation stands, try our MMM Readiness Check, it only takes a few minutes, or explore the principles from this post directly in our interactive MMM Simulator.
Want to watch the full talk, including the Q&A? The recording is available here.
Explore Marketing Mix Modeling consultingQuestions from the Raw & Roasted MMM event.
FAQ on Marketing Mix Modeling consulting
What is Marketing Mix Modeling and how is it used in consulting?
Marketing Mix Modeling (MMM) is a statistical method that measures the contribution of individual marketing channels and external factors to revenue. In consulting engagements, companies use MMM to allocate budgets across channels based on data, rather than relying on gut feeling or incomplete attribution.
How much data do you need for a reliable MMM model?
As a rule of thumb, you need at least two years of weekly data and ten observations per model parameter. With less data, or too many variables, the reliability of the results drops noticeably.
What is PyMC Marketing, and how does it differ from other MMM tools?
PyMC Marketing is an open-source Python library from PyMC Labs for Bayesian Marketing Mix Modeling. It offers ready-made building blocks for adstock and saturation curves, plus built-in budget optimisation, and, like Meridian from Google, returns an uncertainty range rather than a single point estimate. Unlike Meridian, PyMC Marketing is more platform-independent and is increasingly being extended to handle reach and frequency data as well.
Is there a minimum budget share needed for a channel to show up in the model at all?
There’s no fixed rule, but in our project experience the threshold is often around 5 percent of total budget. Below that, and especially below 1 percent, a channel is often not reliably captured by the model. An exception applies to niche providers with an overall smaller advertising budget.
How do incrementality tests or offline sales lift studies change MMM results?
Results from such tests are often built into the model as a prior. This narrows the possible range for a channel’s effect and often noticeably changes the final attribution, typically towards smaller, more precise values for the tested channel.
Does MMM work for B2B companies with one-off campaigns, for example around individual events?
This is more challenging, because MMM relies on sufficient variance in spend. Short, one-off activities often don’t provide enough variation for the model to detect a reliable effect. In practice, two approaches help: aggregating on a monthly rather than weekly basis to bring more continuity into the data series, and a hybrid approach that combines MMM for continuous channels with targeted before-and-after analyses or uplift tests around individual events.